I write these posts. Of course I ask LLMs for feedback, criticism and wordsmithing. Increasingly frustrated by the current flavour of AI slop cringe, I stumbled upon Simon Willison’s tool that highlights LLM cliches: 38 patterns, from “delve” and “testament to” through the tells catalogued in Wikipedia’s Signs of AI writing guide.
I have various levels of AI-ism defence throughout my life and, finding Simon’s tool, took the chance to consolidate them. Now I use 1 corpus of machine-tell writing patterns, a linter that detects and counts them, and staged wiring into every place where an LLM writes prose for human readers.
But it didn’t work.
The slop that most vexes me is a different dialect than Simon’s tells defend against. I call it “fable-speak” and it’s a sort of consultant-y syrup. Simon’s corpus (rightly) targets blog-voice cliches, which bristle, but when I ran it against 24,000 words of prose produced by an automated system I run daily, it produced almost nothing.
Claude (ironically) observed: ‘The house dialect, which Rob named fable-speak, is condensed analyst voice: appositive corrections of the shape “your call, comma, not a detail”, claimed-honesty framings like “the honest read”, whole clauses set in bold, and coined hyphen chains. Four locally-authored patterns now cover it; the measurements that justify each one, and the candidates that were rejected, are in [my local stash] dialect-notes.md.’
At one point I fed it my old writing (including my thesis from 2001) and asked it to find the AI-ism patterns in the stash. My writing from pre-LLM era sat between 0.0 and 0.1 counted hits per 100 words everywhere; the slop corpora sat between 0.4 and 5.8.
For fun, here’s some 2001-era Rob prose that now classifies as “slop”:
- a colon-triple: “described in Figure 11 has three drives: hunger, pain avoidance, and curiosity” – but here there really were three things being enumerated.
- stacked-questions: “when to do it? what to do it to? how long to do it? why do it: what will be the future results?” – a rhetorical enumeration structuring a section. Genuinely using a device slop overuses (once, in 30,000 words).
- a no-chain: “there are no rules, and no way to ask ‘how close did we get?’” – that was an actual statement about two absent things, not a “no fluff, no filler” cadence.
- turns-out: “when that explanation (in the form of a Predictor) turns out to be erroneous” – “turns out to be” used here as a plain verb phrase, not the “Turns out, X” AI reveal.
That last one is a good example of how ‘AI tells’ resist regex.
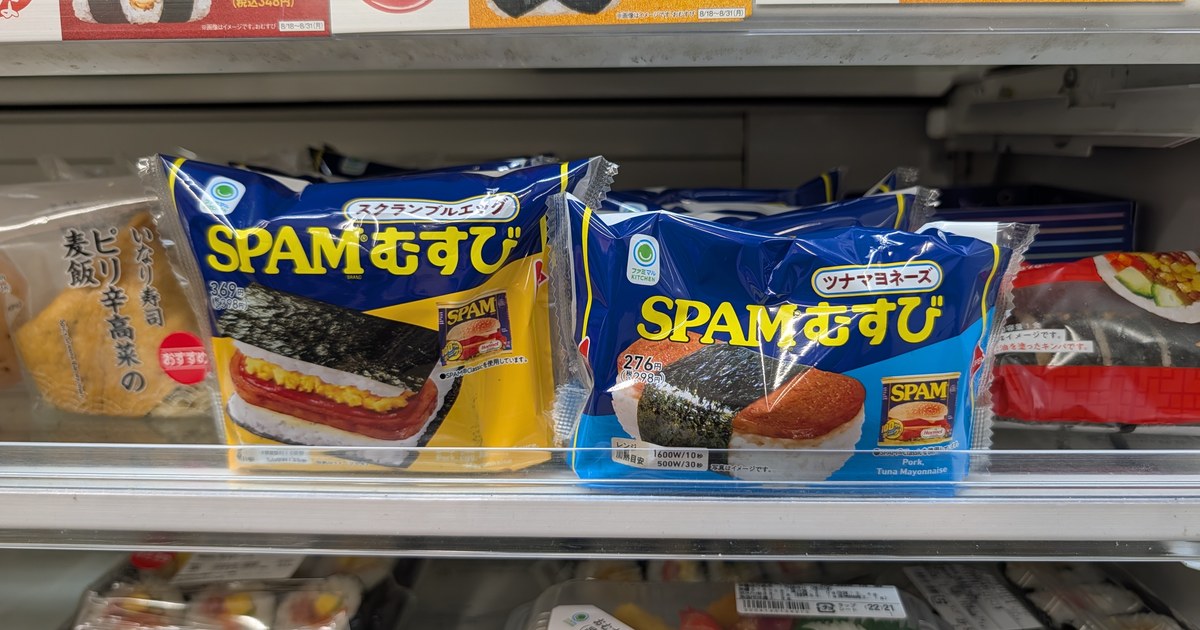
I tried having Claude write this post, in my voice from notes. The cringe was real; I ended up rewriting it top to bottom. Claude’s hook was fun though: it took that Spam photo from our trip to Japan (which is its own side quest full of AI wins I need to write up). Claude ended with “you tell me if the musubi is any good.”